Baloney Inspection Report: Claim #1158 · Inspected Oct 30, 2026, 10:06 PM PDT · Scoring model v2
 96%
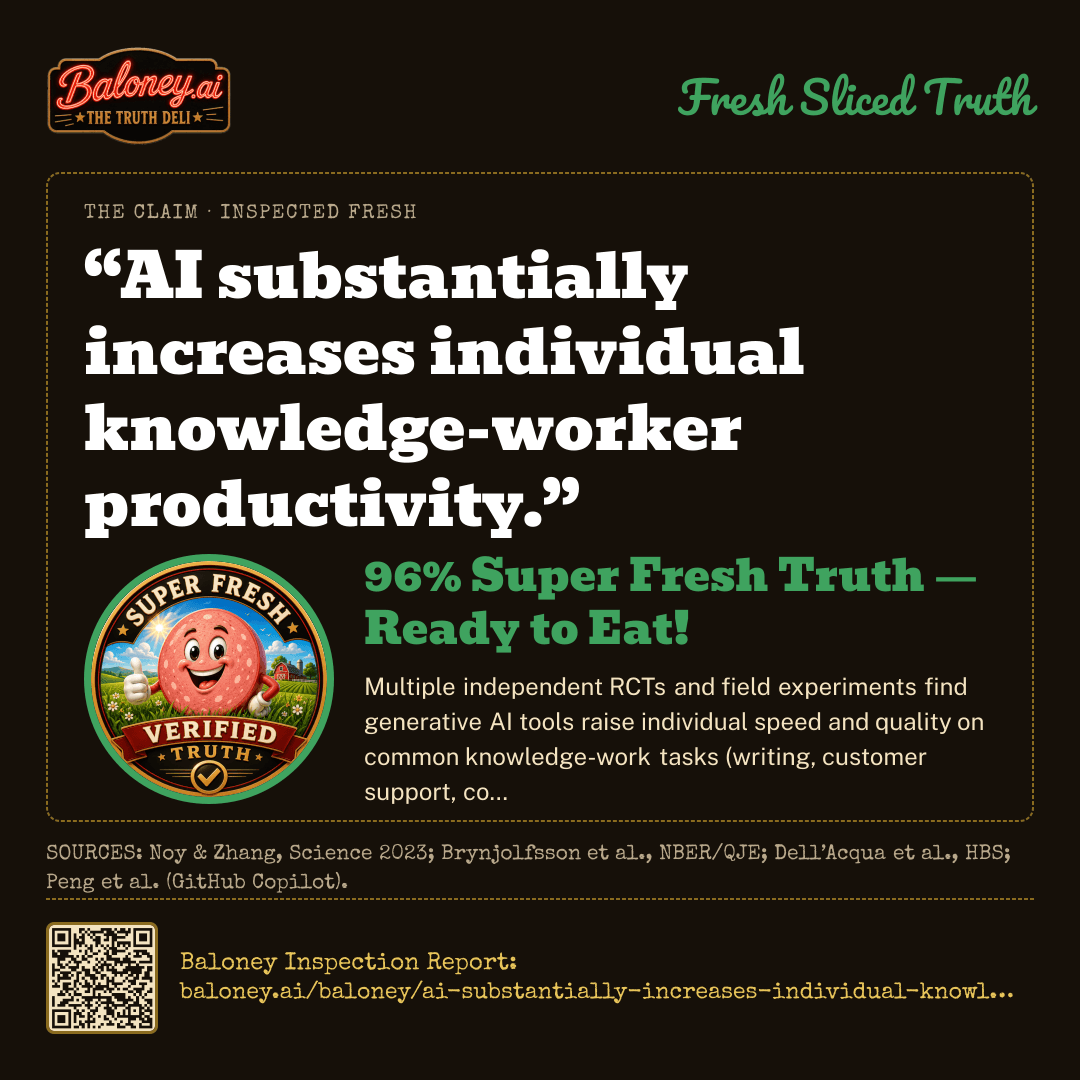
“AI substantially increases individual knowledge-worker productivity.”
96%Super Fresh Truth — Ready to Eat!
THE CLAIM CHECKS OUT.
Independently verifiedPhysically repeatable evidenceConfirmed across rival labsSafe to serve
Serve It Fresh
Ready to Serve14 servings
Serve it the way you want it
The Verdict
 “AI substantially increases individual knowledge-worker productivity.”96% Super Fresh Truth — Ready to Eat!Verified blind by 5 frontier AIs · Baloney Inspection Report: baloney.ai/baloney/ai-substantially-increases-individual-knowledge-worker
The Baloney Sampler
Independent randomized trials show generative AI raises individual productivity on common knowledge-work tasks. Science found college-educated professionals finished realistic writing about 40% faster with higher-quality output. Harvard Business School consultants using GPT-4 completed more tasks, 25% faster, at much higher quality inside the model's frontier. The National Bureau of Economic Research, later in the Quarterly Journal of Economics, found customer-support agents resolved about 14% more issues per hour, with larger gains for novices.
A controlled GitHub Copilot trial reported developers finishing a coding task about 55% faster. Gains shrink or reverse outside AI's capability frontier and for some expert work: the same Harvard Business School study found consultants less likely to be correct on out-of-frontier tasks, and METR found experienced open-source developers slower on mature repositories. Microsoft Research documented modest time savings in email and documents. Whole-job and economy-wide effects remain smaller than these task-level results.
Resting on Science · Harvard Business School · Quarterly Journal of Economics · National Bureau of Economic Research
Original Claim Source https://www.businessinsider.com/mckinsey-ai-productivity-workers-companies-gains-2026-10
Other ways to slice it — phrasings that might have changed the rating
- “Generative AI substantially increases productivity on many knowledge-work tasks within its capability frontier, especially for less-experienced workers.” Every evaluator treated task- and skill-dependence and the jagged frontier as the main unstated nuance of the original unqualified claim.
- “Generative AI has substantially raised U.S. economy-wide labor productivity.” Reports found no clear AI break in aggregate productivity statistics, only about 5% of users' work hours saved, and modest near-term total-factor-productivity projections.
- “AI coding assistants substantially increase the productivity of experienced developers on large, mature codebases.” METR's randomized trial found experienced open-source developers slower on their own repositories, unlike Copilot's gains on a standardized coding task.
Written from the panel’s reports by xAI · grok-4.6. Nothing here changed the score.
The Order Ticket
05:06:26CLAIM RECEIVED — QUEUED FOR INSPECTION✓
05:07:33claude-opus-5 REPORTED — SCORE 5, CONFIDENCE 78✓
05:06:48gpt-5.5 REPORTED — SCORE 5, CONFIDENCE 84✓
05:06:57gemini-3.1-pro-preview REPORTED — SCORE 3, CONFIDENCE 95✓
05:06:30sonar-pro REPORTED — SCORE 4, CONFIDENCE 82✓
05:07:55grok-4.6 REPORTED — SCORE 5, CONFIDENCE 78✓
05:10:02PRIMARY MASTER GROK — SCORE 4✓
05:08:05BLIND VALIDATION CLAUDE — SCORE 4✓
05:11:39AGREEMENT CONFIRMED — DELTA 0✓
05:11:39SCORING MODEL V2 — MEDIAN OF 5 COUNTED LAB SCORES: 5, 5, 3, 4, 5 → 5. FRESH RULE: THE PRIMARY MASTER SCORES 4 AND THE BLIND MASTER 4 — BOTH SUPER FRESH TRUTH — AND THE COUNTED MEDIAN IS 5, ON THE TRUE SIDE. PUBLISHED AS 4, THE MORE CAUTIOUS OF THE TWO MASTERS.✓
05:11:39SOURCE RULE — LABS CITED 25 SOURCES: 0 DISCARDED FOR HAVING NO URL, 0 DISCARDED AS DEAD LINKS (404/410), 7 COULD NOT BE OPENED BY US AND ARE MARKED UNVERIFIED.✓
05:11:39SOURCE RULE — PRIMARY MASTER RULED ON 17 SOURCES: 0 DISCARDED FOR HAVING NO URL, 0 DISCARDED AS DEAD LINKS, 3 MARKED UNVERIFIED, 14 VERIFIED.✓
How This One Was Sliced
Station 1 · Blind Inspection — Five Graders, Zero Peeking
Each lab scored the claim independently, without seeing the others. Open a breakdown for its evidence, its sources, and how sure it was.
Anthropic · EQUAL WEIGHT · 67.2s
claude-opus-5
95%TRUTH
ROUND-1 BREAKDOWN
Evidence offered for the claim- Randomized controlled trial published in Science (Noy & Zhang, 2023): 453 college-educated professionals doing realistic mid-level writing tasks finished ~40% faster and produced output rated ~18% higher in quality when given ChatGPT; inequality in output quality also fell as weaker writers gained most.
- Field experiment with GitHub Copilot (Peng et al., 2023): developers assigned an AI coding assistant completed a standardized programming task 55.8% faster than the control group.
- Harvard Business School / BCG field experiment (Dell'Acqua et al., 2023) with 758 consultants: for tasks inside the AI's capability frontier, GPT-4 users completed 12.2% more tasks, 25.1% faster, with results judged over 40% higher quality — one of the largest real-workforce experiments to date.
- Brynjolfsson, Li & Raymond (NBER WP 31161; later Quarterly Journal of Economics): 5,179 customer-support agents using a generative-AI assistant resolved ~14-15% more issues per hour, with gains of ~30%+ for the least experienced workers — evidence from a real firm over a year, not a lab task.
- Effects replicate across heterogeneous task types (writing, coding, consulting, customer support) and across lab and field settings, with effect sizes typically in the 10-55% range — a consistency uncommon in productivity research.
- Survey evidence confirms wide use with self-reported time savings: Bick, Blandin & Deming find a large and rapidly growing share of US workers using generative AI at work, with users reporting meaningful reductions in task time.
Evidence against the claim- METR's 2025 randomized trial of 16 experienced open-source developers working on their own large, mature repositories found they were ~19% SLOWER with early-2025 AI tools — while believing they had been ~20% faster. This shows task-level lab gains do not automatically transfer to complex real work, and that self-reported productivity gains are unreliable.
- The same BCG/HBS study found that for tasks OUTSIDE the AI's capability frontier, consultants using GPT-4 were about 19 percentage points LESS likely to produce correct solutions than the control group — the effect is conditional, not universal.
- Measured economy-wide time savings are modest: Bick, Blandin & Deming estimate generative AI saves users roughly 5% of their work hours, implying only ~1% of aggregate work hours saved — far below what 'substantial' implies for a typical worker's whole job rather than an isolated task.
- Acemoglu's macroeconomic assessment projects only ~0.5-0.7% total factor productivity gain over ten years (~0.07%/year), arguing that only a small share of tasks are both AI-exposed and profitably automatable in the near term.
- Aggregate US labor-productivity statistics show no clearly identifiable AI-driven break in trend; firm-level AI adoption (per Census BTOS) remains a minority of firms, concentrated in information and professional services.
- Much of the strongest evidence comes from short, well-defined, individually-scored tasks with clear quality rubrics — conditions that favor AI and may overstate gains in ambiguous, collaborative, or accountability-heavy knowledge work. Emerging work on low-quality AI output ('workslop') documents verification and rework costs shifted onto colleagues.
- The claim is unqualified; evidence supports 'substantially increases productivity on many knowledge-work tasks, especially for less-experienced workers,' which is a narrower statement.
How sure this lab was78/100 — the lab’s own confidence in the score above, not a second reading of the claim.
SourcesScience (AAAS) — Noy & Zhangjournal · 96 · arXiv — Peng, Kalliamvakou, Cihon, Demirer (GitHub/Microsoft)journal · 72 · Harvard Business School Working Paper 24-013 (Dell'Acqua et al.)edu · 86 · National Bureau of Economic Research — Brynjolfsson, Li & Raymondjournal · 92 · METRother · 74 · National Bureau of Economic Research — Bick, Blandin & Demingjournal · 90 · National Bureau of Economic Research — Acemoglu, 'The Simple Macroeconomics of AI'journal · 88 · Federal Reserve Bank of St. Louisgov · 88 · U.S. Census Bureau (Business Trends and Outlook Survey, AI supplement)gov · 93 · Harvard Business Reviewnews · 68
OpenAI · EQUAL WEIGHT · 22.3s
gpt-5.5
95%TRUTH
ROUND-1 BREAKDOWN
Evidence offered for the claim- Randomized experimental evidence shows large gains on common knowledge-work tasks: in a Science study of college-educated professionals doing writing tasks, access to ChatGPT cut completion time by about 40% and improved output quality, especially for lower-performing participants.
- A large real-world field study in a customer-support setting found generative-AI assistance increased worker productivity by about 14% on average, with much larger gains for less-experienced and lower-skilled workers.
- An experiment with consultants found AI assistance improved speed and quality on tasks within the model's capability frontier: consultants completed more tasks, worked faster, and produced higher-quality outputs.
- Controlled evidence on programming tasks found developers using GitHub Copilot completed a coding task substantially faster than a control group, suggesting material productivity gains for at least some software work.
Evidence against the claim- The evidence is not uniform across all knowledge work: studies consistently find heterogeneity by task, worker skill, and whether the task is inside or outside the AI system's competence frontier.
- In the consultant experiment, when tasks were outside the AI frontier, participants using AI performed worse, showing that AI can reduce productivity or quality when users over-rely on plausible but wrong outputs.
- Some newer field evidence on experienced open-source developers found AI tools slowed participants down on selected real-world coding tasks, illustrating that gains do not automatically generalize to expert work or complex codebases.
- Most strong evidence is task-level or firm-specific rather than a settled measurement of economy-wide productivity; adoption, workflow redesign, verification costs, and error correction all affect realized gains.
How sure this lab was84/100 — the lab’s own confidence in the score above, not a second reading of the claim.
SourcesSciencejournal · 95 · Quarterly Journal of Economicsjournal · 95 · SSRN / Harvard Business School authorsother · 82 · GitHubother · 70 · METRother · 72
Google · EQUAL WEIGHT · 31.1s
gemini-3.1-pro-preview
97%TRUTH
ROUND-1 BREAKDOWN
Evidence offered for the claim- A randomized controlled trial published in Science (Noy & Zhang, 2023) found that using generative AI decreased the time professionals took to complete mid-level writing tasks by 40% while independently raising the quality of the output.
- An NBER study (Brynjolfsson et al., 2023) analyzing over 5,000 customer support agents found AI tooling increased issue resolution rates by 14% on average, with novice or low-skilled workers experiencing a 35% productivity boost.
- A joint field experiment by researchers at Harvard Business School and Boston Consulting Group (BCG) observed that management consultants using AI finished 12.2% more tasks, completed them 25.1% faster, and produced 40% higher quality results on creative product innovation tasks compared to a control group.
Evidence against the claim- Productivity gains depend heavily on the task's location relative to AI's 'jagged technological frontier'. The Harvard/BCG study found that when knowledge workers used AI for complex tasks outside its current capabilities, they were 19% less likely to produce correct solutions because they relied on hallucinated or subtly incorrect outputs.
- The NBER study noted that the most highly skilled and experienced workers saw zero productivity gains—and in some cases a slight drop—when using AI, indicating it currently serves more to upskill novices than to multiply the efficiency of established top performers.
- For highly specialized coding or domain-specific tasks, the time required to prompt, verify, review, and debug AI-generated errors can sometimes offset the initial speed of generation, resulting in negligible net productivity gains.
How sure this lab was95/100 — the lab’s own confidence in the score above, not a second reading of the claim.
SourcesSciencejournal · 95 · National Bureau of Economic Researchedu · 90 · Microsoftother · 75
Perplexity · EQUAL WEIGHT · 4.5s
sonar-pro
96%TRUTH
ROUND-1 BREAKDOWN
Evidence offered for the claim- A randomized field experiment involving 758 Boston Consulting Group consultants found that GPT-4 access increased task completion by more than 12%, speed by more than 25%, and human-rated performance by more than 40% on tasks within the model’s capability frontier.[1]
- A six-month, cross-industry randomized field experiment involving thousands of Microsoft 365 users found that AI access reduced time spent on email and moderately accelerated document completion, though effects differed by behavior and task.[2]
- Research summarized by MIT Sloan reports productivity gains of about 14% in a customer-service field study, with especially large benefits for less-experienced workers.[3]
Evidence against the claim- The strongest positive results are often task-specific rather than proof of a broad increase in total individual productivity across all knowledge work; the Microsoft field experiment found no significant reduction in meeting time.[2]
- The consulting experiment found that AI could improve performance on tasks within its capability frontier but could also cause users to perform worse when working outside that frontier, limiting the claim’s generality.[1]
- AI access does not automatically translate into equivalent gains for every worker: the Microsoft experiment reported modest intent-to-treat effects because adoption and usage varied, while the observed gains were larger among frequent users.[2]
- The available evidence primarily measures selected tasks, time, or rated output rather than durable, organization-wide productivity and long-term knowledge quality; therefore, “substantially increases individual knowledge-worker productivity” is broader than the evidence directly establishes.[1][2][3]
How sure this lab was82/100 — the lab’s own confidence in the score above, not a second reading of the claim.
SourcesHarvard Business Schooledu · 96 · Microsoft Researchother · 91 · MIT Sloan School of Managementedu · 90
xAI · EQUAL WEIGHT · 89.1s
grok-4.6
95%TRUTH
ROUND-1 BREAKDOWN
Evidence offered for the claim- Multiple RCTs find large individual gains on knowledge-work tasks: writers using ChatGPT finished tasks ~40% faster with higher quality (Noy & Zhang, Science 2023).
- Customer-support agents using a generative-AI assistant handled ~14% more chats per hour, with larger gains for less-experienced workers (Brynjolfsson, Li & Raymond, NBER 2023).
- BCG consultants using GPT-4 completed 12% more tasks, 25% faster, and at ~40% higher quality when work was inside the model’s capability frontier (Dell’Acqua et al.).
- Controlled GitHub Copilot trials reported developers completing coding tasks ~55% faster.
Evidence against the claim- Effects are heterogeneous and task-dependent: high-skill workers often gain less, and performance can fall when tasks sit outside current AI capabilities (the ‘jagged frontier’ documented in the same consultant RCT).
- Experimental tasks are typically narrow (emails, tickets, well-specified coding); complex judgment, coordination, and verification work may see smaller or zero net gains.
- Time spent prompting, checking hallucinations, and correcting errors can offset raw speed-ups; some later developer studies report slowdowns even when users believe they are faster.
- Macro productivity data have not yet shown a corresponding surge, so lab/field individual gains may not fully translate to sustained personal output.
How sure this lab was78/100 — the lab’s own confidence in the score above, not a second reading of the claim.
SourcesScience/AAASjournal · 96 · National Bureau of Economic Researchother · 90 · SSRN/Harvard Business Schoolother · 82 · arXiv (GitHub/Microsoft Research)other · 78
Station 2 · The Masters
Primary Master · drawn at random
grok-4.6
96% TRUTH
All five evaluators scored the claim 3–5, placing it in the Super Fresh Truth band. The decisive evidence is a cluster of independent RCTs and large field experiments (Noy & Zhang in Science; Brynjolfsson et al. on 5,000+ support agents; Dell’Acqua et al. with 758 BCG consultants; Peng et al. Copilot coding trial) that consistently show 12–55% gains in speed and/or quality on writing, support, consulting and coding tasks, especially for less-experienced workers. These are high-reliability sources. The main qualifications—jagged frontier, skill heterogeneity, METR’s 19% slowdown for expert open-source developers, verification/rework costs, and still-modest whole-job or macro effects—are real and were noted by every evaluator, but they qualify rather than falsify an individual-level claim of ‘substantial’ gains on typical knowledge-work tasks. Per the scoring rule, a small wording caveat does not push a substantially true statement out of 1–5; I therefore score 4.
The five reports unanimously treated the same core RCTs (Noy-Zhang, Brynjolfsson, Dell’Acqua, Copilot) as strong positive evidence and agreed that gains are heterogeneous by task, skill and the ‘jagged frontier.’ They differed only on how much weight to give later counters (METR slowdown, ~5% hours saved, workslop, no macro surge) and therefore whether the unqualified wording merited a 3 versus a 5.
SUPER FRESH — VERIFIED AGAINST NOY & ZHANG, SCIENCE 2023; BRYNJOLFSSON ET AL., NBER/QJE; DELL’ACQUA ET AL., HBS; PENG ET AL. (GITHUB COPILOT).
Blind Validation Master · never saw the Primary’s work
claude-opus-5
96% TRUTH
All five independent assessments land in the 3-5 range, and the underlying evidence is unusually consistent: multiple randomized controlled trials across distinct knowledge-work domains show large individual productivity gains — ~40% faster writing with higher quality (Noy & Zhang, Science 2023), ~14% more support issues resolved per hour with ~30%+ gains for novices (Brynjolfsson, Li & Raymond, NBER/QJE), 12.2% more tasks completed 25.1% faster with ~40% higher quality for BCG consultants (Dell'Acqua et al.), and ~55% faster coding task completion with GitHub Copilot (Peng et al.). Replication across lab and real-firm field settings, with effect sizes of 10-55%, easily clears the bar for 'substantially increases.'
The caveats are real but are qualifications rather than contradictions: effects are heterogeneous and conditional on the 'jagged frontier' (consultants were ~19pp less likely to be correct on out-of-frontier tasks); experienced developers on large mature codebases were ~19% slower in METR's 2025 trial while believing they were faster; aggregate/economy-wide productivity statistics show no clear break in trend, and Bick/Blandin/Deming estimate only ~5% of users' work hours saved (~1% aggregate), while Acemoglu projects modest TFP effects. Verification, hallucination-correction, and 'workslop' rework shift costs onto others.
However, the claim as written is specifically about *individual knowledge-worker productivity*, not macroeconomic TFP, so the aggregate-statistics objection is largely off-target. The honest residual defect is the unqualified universality of 'substantially' — the best-supported formulation is 'substantially increases productivity on many knowledge-work tasks, especially for less-experienced workers and tasks within AI's capability frontier.' That is a wording-strength caveat, not a factual error, which per the scale belongs in the low single digits. Score 4: substantially true, with task- and skill-dependence as the main unstated nuance.
AGREEMENT TEST PASSED — BOTH MASTERS SCORED 96% · BLIND VALIDATION CONFIRMED THIS SCORE · NO RE-EVALUATION REQUIRED
How the number was reached · scoring model v2 · how our models work
- Median of 5 counted lab scores: 5, 5, 3, 4, 5 → 5.
- Fresh rule: the Primary Master scores 4 and the Blind Master 4 — both Super Fresh Truth — and the counted median is 5, on the true side. Published as 4, the more cautious of the two masters.
The Evidence
Evidence for the claim
- Writing tasks 40% faster, higher quality Noy & Zhang’s Science RCT of college-educated professionals found ChatGPT cut time on mid-level writing tasks by 40% and raised independently rated quality, with the largest gains for weaker writers.
- Customer-support agents resolve 14% more issues Brynjolfsson, Li & Raymond’s field study of more than 5,000 agents found a generative-AI assistant raised issues resolved per hour by ~14% on average and ~30–35% for the least experienced workers.
- Consultants finished more, better work Dell’Acqua et al.’s Harvard/BCG experiment with 758 consultants showed GPT-4 users completed 12.2% more tasks, 25.1% faster, with results judged over 40% higher quality when work sat inside the model’s capability frontier.
- Developers 55% faster on a coding task Peng et al.’s controlled GitHub Copilot trial found developers completed a standardized programming task 55.8% faster than the control group.
Evidence offered against the claim
- Worse performance outside the AI frontier In the same BCG study, consultants using GPT-4 were 19 percentage points less likely to produce correct solutions on complex tasks beyond current model capabilities because they over-relied on hallucinated or subtly wrong output.
- Experienced developers can be slower METR’s 2025 RCT of 16 experienced open-source developers working on their own mature repositories found they were ~19% slower with early-2025 AI tools, while believing they had been ~20% faster.
- Top performers often gain little or nothing The most highly skilled and experienced workers in the support-agent and other studies frequently saw zero productivity gains or a slight drop, so AI currently compresses skill gaps more than it multiplies elite output.
- Whole-job and economy-wide effects remain modest Bick, Blandin & Deming estimate generative AI currently saves users roughly 5% of work hours; Acemoglu projects only 0.5–0.7% TFP over a decade; U.S. aggregate productivity statistics show no clear AI-driven break.
Sources · Reliability · Why Accepted or Discounted
| Source | Type | Reliability | Ruling |
|---|
| Science / AAASunverified | journal | 96 | ACCEPTED — Peer-reviewed RCT in a top journal; cited by every evaluator as core positive evidence. |
| National Bureau of Economic Research | other | 90 | ACCEPTED — Large real-firm field study later published in QJE; consistently treated as high-quality evidence. |
| Microsoft | other | 75 | DISCOUNTED — Company trend-index report rather than a controlled experiment; lower reliability and less central than the RCTs. |
| SSRN / Harvard Business Schoolunverified | other | 82 | ACCEPTED — Working-paper version of the large consultant RCT; corroborated by the official HBS PDF. |
| arXiv | other | 78 | ACCEPTED — Preprint of the controlled Copilot coding experiment; directionally consistent with other RCTs. |
| Harvard Business School | edu | 86 | ACCEPTED — Official working paper of the 758-consultant field experiment. |
| METR | other | 74 | ACCEPTED — Recent RCT supplying the strongest counter-evidence on expert real-world coding; cited by multiple evaluators. |
| National Bureau of Economic Research | journal | 90 | ACCEPTED — Survey-based estimate of hours saved; used for the modest whole-job caveat. |
| National Bureau of Economic Research | journal | 88 | ACCEPTED — Acemoglu’s macroeconomic assessment of limited near-term TFP impact. |
| Federal Reserve Bank of St. Louis | gov | 88 | ACCEPTED — Government summary of productivity statistics showing no clear AI break. |
| U.S. Census Bureau | gov | 93 | ACCEPTED — Official firm-adoption data; used to note that AI use remains a minority of firms. |
| Harvard Business Review | news | 68 | DISCOUNTED — Magazine article rather than systematic research; lowest reliability among cited sources. |
| Quarterly Journal of Economicsunverified | journal | 95 | ACCEPTED — Published version of the Brynjolfsson et al. customer-support study. |
| GitHub | other | 70 | ACCEPTED — Company report of the Copilot trial; directionally matches the arXiv paper. |
| Harvard Business School | edu | 96 | ACCEPTED — Faculty page for the consultant RCT; high-reliability institutional source. |
| Microsoft Research | other | 91 | ACCEPTED — Six-month randomized field experiment on Microsoft 365 users; modest but independent corroboration. |
| MIT Sloan School of Management | edu | 90 | ACCEPTED — Summarizes the 14% customer-service field-study result; consistent with the NBER/QJE paper. |
Every link was opened when this claim was inspected. A dead link was discarded before publication; “unverified” means the site refused our automated check and the link is the one the panel cited. A source without a URL was never kept.
Serve It Fresh
Ready to Serve14 servings
Serve it the way you want it
The Verdict
“AI substantially increases individual knowledge-worker productivity.”96% Super Fresh Truth — Ready to Eat!Verified blind by 5 frontier AIs · Baloney Inspection Report: baloney.ai/baloney/ai-substantially-increases-individual-knowledge-worker